
Visual intelligence is imperative for artificial intelligence (AI) in imaging. It recognises and differentiates objects and humans in a video or image. To achieve this, the model needs training and testing through computer vision algorithms. The higher the annotation quality, the better the visual intelligence of the AI model.
Image annotation is a complex and meticulous task, which, if executed correctly, can yield results tailored to your business objectives. However, low-quality image annotation can drive up operational costs without producing tangible results.
This article lists image annotation types and methods, explains use cases, and highlights the role of visual intelligence.
What is visual annotation?
Visual annotation, also called image annotation, is the process of labelling objects, regions or features in images and video so that computer vision models can learn to recognise them. Labels range from a single tag for a whole image to pixel-level outlines of every object, and together they form the training data used in image annotation for machine learning.
Types of image annotation
During annotation, you add metadata to the dataset. The following image annotation types train high-performing machine-learning models:
Image classification
Image classification, also called ‘tagging,’ identifies similar objects across the dataset. It refers to an object in a labelled image and recognises a similar one in an unlabelled image. This classification type is broad and only identifies the basic nature of the object.
For example, an annotator could tag an image of an office as a ‘meeting room’ or ‘coffee station’.
Object recognition/detection
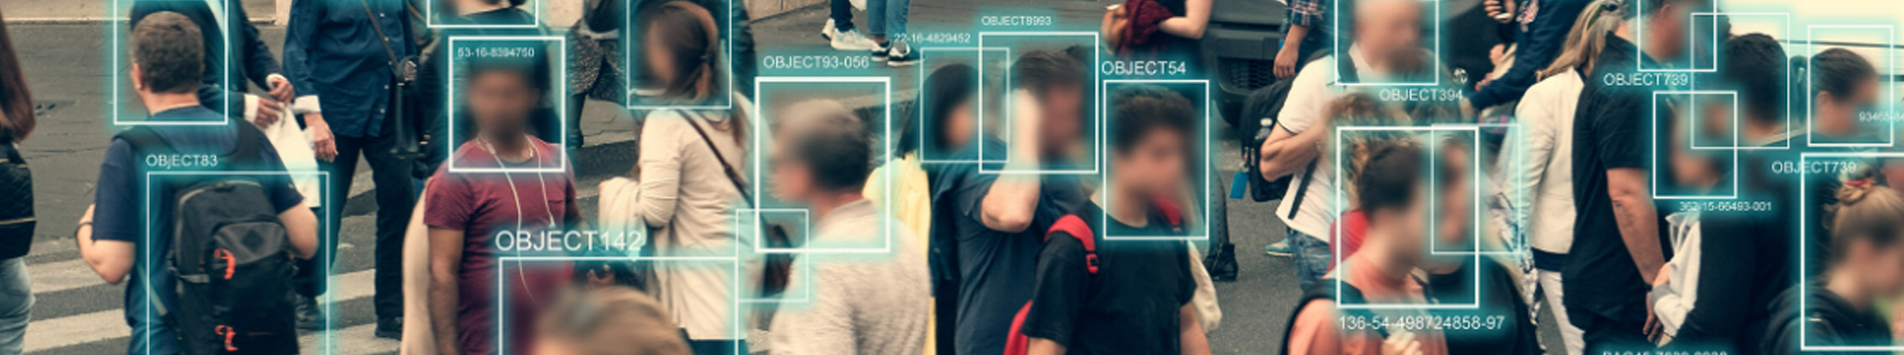
Object detection identifies an object’s presence, location, and count. The annotator uses different polygons to differentiate objects within an image. At a more advanced and complex level, a case of object recognition is medical imaging like CT (Computed Tomography) scan or MRI (Magnetic Resonance Imaging).
This is useful in medical science to identify tumours and other malignant growth and track changes over time.
Boundary recognition
Boundary recognition identifies the edges of an object, topography, and artificial boundaries in an image. For example, it identifies lines and splines in traffic lanes and sidewalks, and land borders, which helps train autonomous vehicles, trains and drones to navigate.
Segmentation annotation
Segmentation annotation labels images at the pixel level rather than with boxes, giving models the exact shape of each object. This is an advanced technique that determines how similar or different the objects in an image are and how they change over time. Three image segmentation types are:
- Semantic segmentation: Ideal for grouping similar objects that do not need counting. For example, the crowd and the team in a baseball match.
- Instance segmentation: This is a pixel-wise segmentation that can count the number of people in the crowd in the example above.
- Panoptic segmentation: It blends both the techniques above to deliver data that is labelled for both semantic and instance segmentation.
Image annotation methods
Depending on your requirements and annotation tool, you can use one or more of these methods:
- Bounding box: Annotators draw a 2D or 3D box around objects, such as vehicles, road signs, and pedestrians. The shape of the object or occlusion is less critical.
- Landmarking: Annotators plot an object’s characteristics to detect emotions, expressions, and features. This method is helpful in facial recognition applications.
- Polygon labelling: Annotators mark each of the points to trace the outline of an object. This method helps where the exact shape of the object is important, such as a house or vegetation.
- Polyline: Annotators draw connected lines to mark lanes, pipelines, power lines or road edges.
- Cuboid: Annotators draw 3D boxes that capture an object’s length, width and depth, which helps with depth perception.
- 3D point cloud: Annotators label points captured by LiDAR (light detection and ranging) sensors to give autonomous systems a 3D view of their surroundings.
Image annotation use cases
Let us understand the image annotation types and methods with the help of practical use cases:
Automotive industry
Annotate vehicles, sky, roads, trees, road signs, and other objects to help autonomous cars navigate safely. For example, the vehicle can easily differentiate between a human and a tree.
Security
Annotated images train models that monitor restricted areas, detect unattended objects and control access to secure sites. Any use of facial recognition needs careful governance: the EU Artificial Intelligence Act, for example, prohibits real-time remote biometric identification in publicly accessible spaces for law enforcement, except in narrowly defined cases.
Retail
A large retail shop could use 2D or 3D bounding boxes. Object detection algorithms can perform visual searches to determine the availability and quantity of items.
Real estate
Images of housing and commercial real estate have different 3D objects that the annotator can identify using segmentation and the cuboid tool. It creates depth and scales each object in an image.
Healthcare
Annotators label X-rays, CT and MRI scans to train models that flag tumours, fractures and other abnormalities for clinicians to review. These projects need annotators with clinical knowledge and strict privacy controls. Learn more about medical image annotation.
Financial services and insurance
Image annotation trains models that read cheques, identity documents and invoices, and that assess vehicle or property damage from photos for insurance claims. This speeds up processing and helps flag suspected fraud.
Robotics
Warehouse, manufacturing and service robots rely on annotated images and 3D data to recognise objects, estimate depth and grasp items safely. Cuboid and keypoint annotation are common here.
Agriculture
Drone and satellite images annotated for crop health, weeds and livestock help farmers target water, fertiliser and treatment where they are needed.
Image annotation has applications in a wide range of industries, including fashion, livestock, advertising and marketing, robotics and automation, sports, medicine, insurance, and waste management.
Visual intelligence for image annotation
High-quality annotated data is not readily available. It requires skilled annotators working on tools that give visual intelligence to machine learning models. Much of this data is proprietary and cannot be sourced from public datasets.
Imparting visual intelligence in machine learning models involves collecting and annotating raw data captured through still and video cameras.
Most programmes now combine AI-assisted pre-labelling with human review: a model suggests labels, and trained annotators correct them and handle edge cases. For quality and consistency tips, see our guide to image annotation best practices.
How can Infosys BPM help?
Build high-quality training data for AI at scale using a software and humanware model. The model successfully annotates images, text, audio, video, and sensor data in CPG, retail, media, railways, oil and gas, insurance, healthcare, and financial services. Infosys BPM handles more than 150 million image annotations a month at more than 98% accuracy, with work ranging from HD image and point cloud annotation for a global technology company to drone image segmentation for an Australian mining company.
Read more about the image segmentation annotation service at Infosys BPM.
Frequently asked questions
The terms are often used interchangeably. Labelling usually means assigning a class to an image or object, such as "car" or "tree", while annotation is broader and also covers drawing shapes, marking points and adding other metadata that tells a model where and what an object is.
It depends on the method. Tagging a whole image takes seconds, a bounding box a little longer, and a detailed polygon or segmentation mask can take several minutes per image. AI-assisted pre-labelling and trained annotators shorten this considerably on large projects.
Image annotation labels single, still frames. Video annotation labels objects across a sequence of frames and tracks them as they move, which adds work such as keeping object IDs consistent over time.
Images that show faces, licence plates or other identifying details can be personal data under laws such as the General Data Protection Regulation (GDPR). Teams usually blur or anonymise these details where possible and annotate the data in secure, access-controlled environments.